Top 10 Open Source Web Scraping Frameworks 2026
Take a Quick Look
A 2026 ranking of the top 10 open source web scraping frameworks, judged on maintenance, ecosystem, scale, and fit for AI-era data pipelines.
Top 10 Open Source Web Scraping Frameworks 2026
Open source scraping frameworks do the unglamorous work behind most data products: scheduling requests, retrying failures, parsing pages, and pushing clean records downstream. The 2026 field is broader than it was a few years ago, split between mature crawler frameworks, browser-driven libraries, and lightweight single-language tools.
This ranking covers ten projects that are genuinely open source scraping frameworks. Each entry notes what the project is, who maintains it, and where it fits. A cloud browser API such as AdsCrawl sits outside this category, but it appears once below as a complement for teams whose bottlenecks are JavaScript rendering and anti-bot defenses rather than crawling logic.
How These Frameworks Were Evaluated
First viewport screenshot of scrapy.org.
Rankings are judgment calls, so the criteria are stated up front. Each project was scored on:
- Maintenance health: recent releases, responsive issue triage, and a clear maintainer (community, foundation, or company).
- Ecosystem depth: plugins, middleware, proxy and storage integrations, and documentation quality.
- Scale behavior: concurrency model, memory profile, and evidence of production use at volume.
- Extensibility: how easily the core can be adapted to custom pipelines, queues, and output formats.
- Learning curve versus payoff: setup cost weighed against what the framework saves over hand-rolled requests.
- 2026 relevance: support for headless browsers, async I/O, and AI-assisted development workflows.
Popularity signals such as GitHub stars are treated as context, not proof. A framework with fewer stars but steady releases and a focused maintainer can outrank a larger but stalled project.
The Top 10 Open Source Web Scraping Frameworks, Ranked
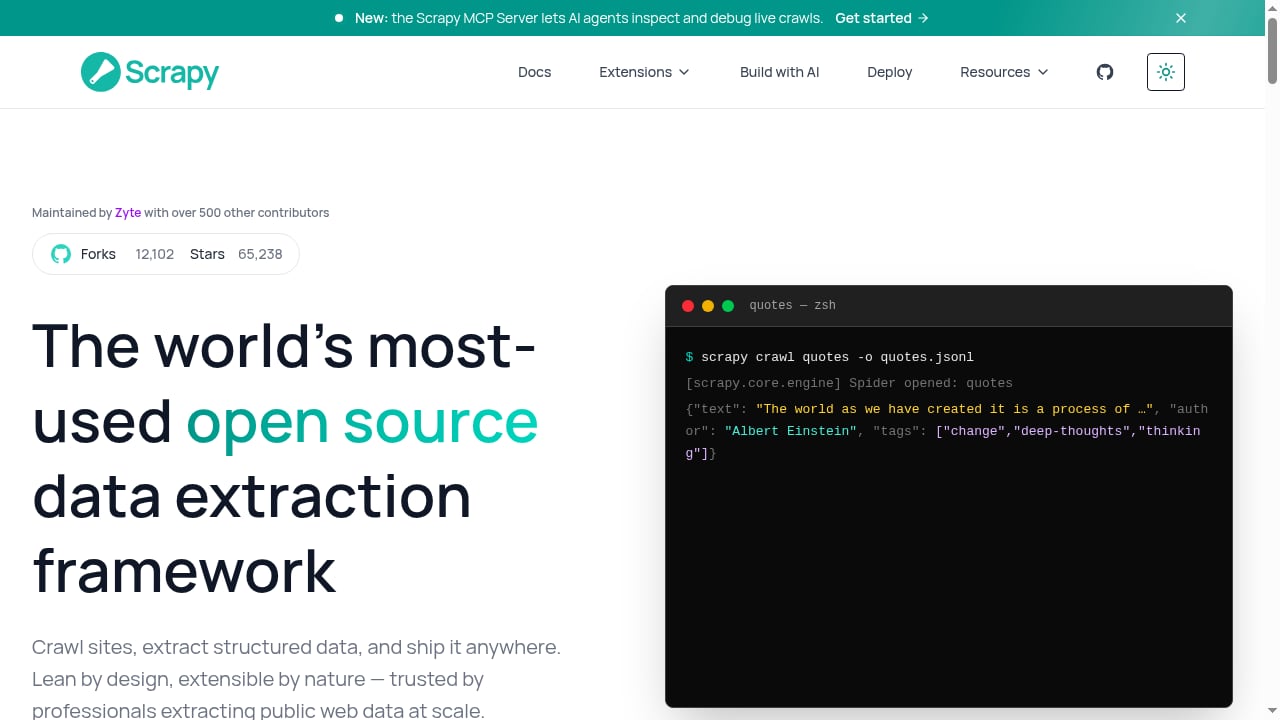
First viewport screenshot of scrapy.org.
1. Scrapy
Language: Python · License: BSD · Maintainer: Zyte and community contributors
Scrapy remains the reference implementation of a scraping framework. It handles crawling, request scheduling, retries, item pipelines, and export in one package, and it is lean by design rather than bundled with a browser. Browser rendering arrives through extensions such as scrapy-playwright, while monitoring, anti-ban tooling, and managed deployment come from the surrounding ecosystem, including Scrapy Cloud by Zyte.
The project's maturity is its strongest evidence: more than 15 years in production, over 500 contributors, roughly 65.2k GitHub stars and 12.1k forks. In 2026 it has also adapted to AI-assisted workflows through Agent Skills for building spiders and a Scrapy MCP Server that exposes scraping capabilities to AI agents. If you need a general-purpose crawler with a long support horizon, this is the default starting point.
2. Crawlee
Language: JavaScript/TypeScript, Python · License: Apache-2.0 · Maintainer: Apify
Crawlee packages the hard parts of browser and HTTP crawling into one library: request queues, autoscaling, session management, retries, and storage. Its distinguishing feature is a unified interface across Cheerio, Playwright, and Puppeteer, so a team can start with static HTML parsing and switch to a real browser only where needed. The dual JavaScript and Python distribution makes it the strongest option for Node-first teams that do not want to adopt a Python stack.
3. Playwright
Language: JavaScript/TypeScript, Python, Java, .NET · License: Apache-2.0 · Maintainer: Microsoft
Playwright is a browser automation library rather than a crawler, but in practice it is one of the most-used foundations for scraping JavaScript-heavy sites. It ships Chromium, Firefox, and WebKit engines, strong network interception, and reliable auto-waiting. It lacks built-in crawl scheduling and item pipelines, which is why it is often paired with Crawlee or wrapped in a custom harness. Ranked third because that missing layer is real work, not a footnote.
4. Beautiful Soup
Language: Python · License: MIT · Maintainer: Community (Leonard Richardson)
Beautiful Soup is a parser, not a crawler, and it earns its place because so many pipelines still rely on it for tolerant HTML and XML parsing. It handles malformed markup gracefully, supports multiple parser backends, and is easy to teach. It will not fetch pages, manage concurrency, or retry failures, so it belongs inside a larger system rather than at its center.
5. Colly
Language: Go · License: Apache-2.0 · Maintainer: Community (gocolly)
Colly brings Scrapy-style concepts to Go: a collector with callbacks, request limits, caching, and optional headless browser integration. Its appeal is operational simplicity. A single compiled binary with low memory overhead is attractive for teams deploying scrapers as small services or scheduled jobs in container environments.
6. Puppeteer
Language: JavaScript/TypeScript · License: Apache-2.0 · Maintainer: Chrome DevTools team
Puppeteer controls Chrome and Firefox over the DevTools Protocol and remains the most direct route to Chrome-specific behavior. It is excellent for pages that depend on real browser rendering, PDF generation, and screenshot capture. Like Playwright, it is a browser driver first; crawl orchestration is left to the developer or to a framework built on top of it.
7. Selenium
Language: Java, Python, C#, Ruby, JavaScript · License: Apache-2.0 · Maintainer: Software Freedom Conservancy
Selenium is older and heavier than the newer browser libraries, but its WebDriver standard and language coverage keep it relevant in enterprises with existing test infrastructure. Teams already using Selenium for QA can reuse grid infrastructure for scraping. The trade-off is more boilerplate and slower iteration than Playwright or Puppeteer.
8. Cheerio
Language: JavaScript/TypeScript · License: MIT · Maintainer: Cheerio contributors
Cheerio implements a jQuery-like API over parsed HTML and is the parsing layer inside many Node scraping stacks, including Crawlee's HTTP crawler. It is fast because it does not run a browser. Used alone it is only a parser; used with a fetcher, it covers a large share of static-site scraping needs with minimal overhead.
9. MechanicalSoup
Language: Python · License: MIT · Maintainer: Community
MechanicalSoup combines the requests library with Beautiful Soup to automate form submission and simple navigation. It is a good fit for small, well-behaved sites and login flows that do not require JavaScript. It is deliberately minimal and should not be expected to handle large crawls or dynamic rendering.
10. Heritrix
Language: Java · License: Apache-2.0 · Maintainer: Internet Archive
Heritrix is an archival web crawler built for breadth and fidelity rather than data extraction. It is the engine behind large-scale web archiving and offers fine-grained control over crawl scope and politeness. Most commercial scraping teams will not need it, but for compliance-sensitive archival work it has few peers.
Comparison at a Glance
First viewport screenshot of scrapy.org.
| Framework | Best for | Browser rendering | Crawl scheduling built in |
|---|---|---|---|
| Scrapy | General-purpose production crawling | Via extension | Yes |
| Crawlee | Node/Python teams wanting batteries included | Yes | Yes |
| Playwright | JavaScript-heavy sites, testing reuse | Yes | No |
| Beautiful Soup | Tolerant HTML parsing | No | No |
| Colly | Lightweight Go services | Optional | Yes |
| Puppeteer | Chrome-specific automation | Yes | No |
| Selenium | Enterprise WebDriver stacks | Yes | No |
| Cheerio | Fast static HTML parsing in Node | No | No |
| MechanicalSoup | Simple Python form workflows | No | No |
| Heritrix | Web archiving at scale | No | Yes |
Choosing Between Them
First viewport screenshot of www.adscrawl.net.
Start with the question you are actually answering. If you need a complete crawler with pipelines and exports, Scrapy and Crawlee are the two strongest general-purpose choices, split mainly by language preference. If your target sites are JavaScript applications, pair a browser library such as Playwright or Puppeteer with a crawl layer rather than building scheduling from scratch. If you are parsing HTML you already have, Cheerio or Beautiful Soup will do the job faster than any full framework.
Language fit matters more than benchmark charts. A Go team will be more productive with Colly than with a Python framework it cannot operate comfortably. Similarly, an organization with Selenium grids already deployed should weigh reuse against the developer-experience gains of newer tools.
One boundary worth naming: open source frameworks give you the crawling logic, not the network. When blocking, CAPTCHAs, or authenticated sessions become the limiting factor, teams often keep their framework and route browser work through a managed cloud browser layer. AdsCrawl is one such option, offering remote Chromium sessions, proxy routing, and CDP access that a Scrapy or Crawlee pipeline can call when a page needs a real browser. For a broader view of that adjacent category, see the Top 10 Browser Automation API Products 2026, and for a direct comparison of tooling styles read AdsCrawl vs Playwright vs Stagehand.
Practical Starting Points
- Prototype fast, then harden: begin with
requestsplus Beautiful Soup to confirm the data is extractable, then port the logic into Scrapy or Crawlee once volume grows. - Respect robots and rate limits: every framework above supports delays and concurrency caps; use them before reaching for proxies.
- Version your spiders: scraping code breaks when markup changes, so keep selectors in tests and alert on empty results.
- Separate fetching from parsing: this makes it easier to swap in a browser or a managed browser API later without rewriting parsers.
Related reading
- BrowserCloud Review: Browser Automation for AI Apps - An evidence-based review of BrowserCloud for AI apps. Compare use cases, strengths, limits, pricing signals, setup, and decision criteria.
- How to Use AdsCrawl with browse.sh: AI Browser Workflows - Learn how to combine AdsCrawl's browser automation API with browse.sh skills to give AI agents reliable, reusable web workflows at scale.
Sources and further reading
- 10 Best Summer Vacation Ideas (2026): Spots That Deliver - Summer vacation ideas ranked: beach weeks, family wins, cool-weather escapes and Europe done right - the 10 best summer vacation spots with costs and timing.
- 23 Best Summer Vacation Destinations - Travel - Jul 19, 2026 · Explore unforgettable summer vacation ideas, from European river cruises to Caribbean escapes, with expert …
Frequently Asked Questions
Is Scrapy still the best open source scraping framework in 2026?
For Python teams building general-purpose crawlers, yes. Its maturity, contributor base, and extension ecosystem remain unmatched. Crawlee is the closest competitor and is often the better pick for JavaScript and TypeScript teams.
Do I need a browser automation tool to scrape websites?
Only for pages that render content with JavaScript or require interaction. Many sites still serve usable HTML, and parsing that directly is faster and cheaper. Use Playwright, Puppeteer, or a managed browser service selectively.
Are these frameworks free for commercial use?
All ten use permissive licenses (BSD, MIT, or Apache-2.0) that allow commercial use. Costs appear later through hosting, proxies, browser infrastructure, or paid support and managed platforms.
What is the difference between a framework and a library here?
Frameworks such as Scrapy, Crawlee, Colly, and Heritrix manage the crawl lifecycle for you. Libraries such as Beautiful Soup, Cheerio, Playwright, and Puppeteer provide capabilities you assemble yourself.
Can I combine an open source framework with a cloud scraping service?
Yes, and it is common. The framework handles scheduling and parsing while a service handles browser rendering, proxies, or session management. AdsCrawl's cloud browser API is designed for that second role, and its integration with DataImpulse proxies shows how the network layer can be swapped independently.
Conclusion
Scrapy leads this list because it has survived long enough to become infrastructure, but the right choice depends on your language, your target sites, and how much orchestration you want to own. Crawlee is the strongest modern alternative, Playwright and Puppeteer are the rendering workhorses, and the lighter parsers remain useful inside larger systems. Pick the smallest tool that covers your crawl, and add managed browser capacity only when the open source layer stops being the bottleneck.
For further reading, the Scrapy documentation and the Crawlee documentation are the most reliable starting points, and the Playwright documentation covers browser-side scraping patterns in detail.